


Why a panel
Different models miss different things.
Running them as an adversarial panel — each seeing the others' findings and arguing — surfaces more real issues and filters more false positives than any single reviewer. The research-backed lever is vendor heterogeneity, not more rounds. A free local/open-weight model adds a different perspective at zero marginal cost, and a CLI seat runs the vendor's own agent — not a raw model API call.
Measured on a small labeled benchmark (v1.1.0, 2026-06-05; 5 fixtures, 3 seeded bugs, one run): the four-vendor panel caught 3/3 seeded bugs vs 2/3 for the best single model (Claude, Qwen; Codex and Agy 1/3), at lower precision: 0.75, and 0.60 for the full jury, against 1.00 for every model run alone. More reviewers found more bugs and raised more false alarms. Small N, directional, not yet repeated on the current release. See the benchmark →
Pipeline
How a run plays out
Round 1 → adaptive debate → verification → one synthesized verdict.
Every agent reviews the diff
All available agents review the same diff concurrently against the same rubric — no agent sees another's work yet.
The panel debates
Each agent sees the others' reviews and emits agree / dispute / missed. With early_stop, a unanimous panel skips the round.
The chair re-judges findings
False positives are dropped, and the report keeps the evidence behind every finding that survives.
One verdict, one report
The chair consolidates consensus, disputed, and single-reviewer findings into a single verdict plus a CI gate — or let the panel decide by --decision vote. Point the same jury at an issue with --issue to check it for completeness.
Integrations & Ecosystem
Installs into the tools you already use.
One unified multi-agent orchestrator: 6 AI coding CLIs • 8 hosted LLM backends • 2 local engines • 6 CI/CD & dev tools. Universal compatibility, on-device or cloud, MIT-licensed.
Interactive
Build your jury
Pick a panel and depth — the flow and generated jury.toml
update live. Hit Run review to watch a scripted run play out on a sample diff.
(Illustrative; nothing runs in your browser.)
Quickstart
From zero to a verdict
brew install berkayturanci/ai-jury/ai-jury
One command via Homebrew or pipx install ai-jury. Stdlib-only.
jury init
Detects your installed agent CLIs and local models, writes a valid jury.toml.
jury --pr 123
3a — convene the panel on a PR: debate, verify, one synthesized verdict.
jury --issue 42
3b — or review an issue for completeness & clarity (READY / NEEDS-INFO / UNCLEAR).
More commands
# install once (Homebrew, curl, or pipx)
brew install berkayturanci/ai-jury/ai-jury
curl -fsSL https://ai-jury.dev/install.sh | sh
pipx install ai-jury

jury init                             # scaffold jury.toml (detects agents + local models)
jury init --wizard                    # guided setup: numbered questions, every one skippable
jury init --preset offline            # free, local-only ($0); also: fast / balanced / thorough
jury config show                      # see the effective config that will run
jury --pr 123                         # review a GitHub PR
jury --pr 123 --post --post-progress  # live: a sticky PR comment updated each round
jury --pr 123 --live                  # stream each step to the terminal as it lands
jury --pr 123 --decision vote         # verdict by panel vote instead of a single chair
jury --pr 123 --auto                  # auto-depth: scale rounds/verify to the diff

jury --issue 42                       # review an ISSUE for completeness (READY/NEEDS-INFO/UNCLEAR)
jury --issue 42 --decision vote       # issue verdict by panel vote (NEEDS-INFO > UNCLEAR > READY)
jury --issue 42 --post                # post the verdict back to the issue thread
jury --issue 42 --live --post         # stream + post each step to the issue as it lands

jury --pr 123 --ci --fail-on critical,major # gate CI on blocking findings (exit 1)
jury --pr 123 --no-min-vendors       # accept a panel that collapsed to one vendor (else exit 3)

jury run-agent --agent claude --role review --prompt-file p.md
                                      # one agent, one role, one JSON result (for an orchestrator)
Requires Python 3.11+ and at least one reviewer seat — an agent CLI (claude,
codex; agy opt-in only),
a free local model via Ollama, or a hosted API. A hosted-API key (ANTHROPIC_API_KEY /
OPENAI_API_KEY / GEMINI_API_KEY) needs no CLI install, but it seats
nothing on its own: add an [[agent]] seat for it to jury.toml.
gh is needed for --pr / --issue and for posting comments.
Configuration
Scaffold it, inspect it, then go
A run is driven by a jury.toml (or built-in defaults). Don't hand-write it the first time — every field is in the configuration reference.
Set up & inspect
jury init                   # scaffold
jury init --wizard          # guided Q&A (skippable)
jury init --preset balanced # or fast/offline/thorough
jury init --list-agents     # CLIs available
jury init --list-models     # local Ollama models
jury config show            # effective config
jury --doctor               # readiness + steps
jury --doctor --json        # the same facts as one JSON document
A jury.toml
[jury]
rounds = 2          # 1 = review, 2 = + debate
chair  = "claude"   # who synthesizes
verify = true       # drop false positives

[[agent]]
name   = "claude"
vendor = "anthropic"
command = "claude"

[[agent]]              # free, offline reviewer
name   = "qwen"
vendor = "local"
model  = "qwen2.5-coder:7b"
endpoint = "http://localhost:11434/v1"rounds1 = independent review only · 2 = + a debate round. With early_stop / max_rounds, a unanimous panel stops early.chairWhich reviewer verifies the findings and synthesizes the final verdict. Unset, it is claude in the built-in defaults and the first [[agent]] of a jury.toml; when the named chair cannot run, the first usable agent takes over.decisionchair (default) lets the chair decide, or vote tallies the panel — majority wins, ties resolve to the stricter stance. The --decision flag. Works for PRs and issues.verifyThe chair judges each candidate finding against the diff to drop false positives — evidence is kept in the report.auto_depthScales rounds & verify to the diff — docs-only → shallow, security-touching → full. The --auto flag.[[agent]]Per reviewer: vendor, command, extra_args; for a local seat use vendor = "local" + endpoint + model.timeout · retriestotal_timeout / phase_timeout / retries bound a run; results can be cached and reviews made incremental.[jury.diff]Lockfiles and generated files are filtered out; a diff still over max_bytes is refused unless you opt in to chunking (chunk = true / --chunk). [jury.context] is diff-only by default with secret redaction on.[jury.ci]Four keys: fail_on (severities that fail --ci), ignore_unverified, min_vendors — the cross-vendor guard — and min_reviews, a panel-size floor that is off at its default 0. Report format is a flag (--format), not a key here.min_vendorsDistinct vendors that must have contributed a review before the run counts as cross-vendor consensus. Ships at 2: fewer, and the run exits 3 — its own code, so a collapsed panel never reads as a clean pass. It only applies once that many vendors are enabled, so a deliberate one-CLI setup is untouched; --no-min-vendors (or min_vendors = 0) accepts a collapsed panel, --strict fails at startup on a missing CLI instead.
Start from a preset — jury init --preset fast|balanced|thorough|offline — then tweak. CLI flags
override the file per run (--rounds, --verify, --auto, --chair, --decision). Validate with
jury --config-validate; --strict-config turns warnings into errors. An optional, trusted
.jury/policy.toml adds high-risk paths, focus areas, and severity overrides — kept separate from jury.toml.
Built in
Everything a review needs
Free & offline option
Add a local open-weight model (Ollama, llama.cpp, vLLM, LM Studio) as a panel seat — zero cloud cost, fully offline, or mixed with cloud CLIs for diversity.
Follow the run live
--live streams every step to your terminal as it lands; --transcript/--verbose render the full play-by-play; --post-progress keeps a sticky PR comment updated each round; --post-mode phased posts Round 1 / debate / decision separately.
Secure by default
Reviewers read attacker-controlled diffs. The claude seat gets no tools at all; codex runs -s read-only but can still read files; agy is opt-in only, because its sandbox does not confine it. Native reviewers start in an empty directory, not your repo. diff-only context plus secret redaction are on by default.
Cost-aware
--auto scales rounds/verify to the diff (docs-only → shallow; security-touching → full); opt in to --chunk for a diff over budget and --cache to reuse results.
CI citizen
--ci --fail-on gates merges; --format json|sarif for code scanning; inline + summary PR comments; opt-in classification labels.
Drop-in skill
Install as a plugin in Claude Code, Codex, Antigravity or Cursor — each with its own route and its own update path, and Cursor's is a git checkout because it has no CLI install command — or copy the skill into .claude/skills/. All four, with what each route registers: docs/install.md.
Watch it deliberate
Theater mode
--theater is an opt-in, animated view of a live run: the
models take their seats around a table and speak in turn as the run moves through
review → debate → verify, then decide together — by panel vote or recorded by the chair.
No judge; the jurors deliberate with each other. It's driven by the real
on_event stream, so it always reflects the actual run.
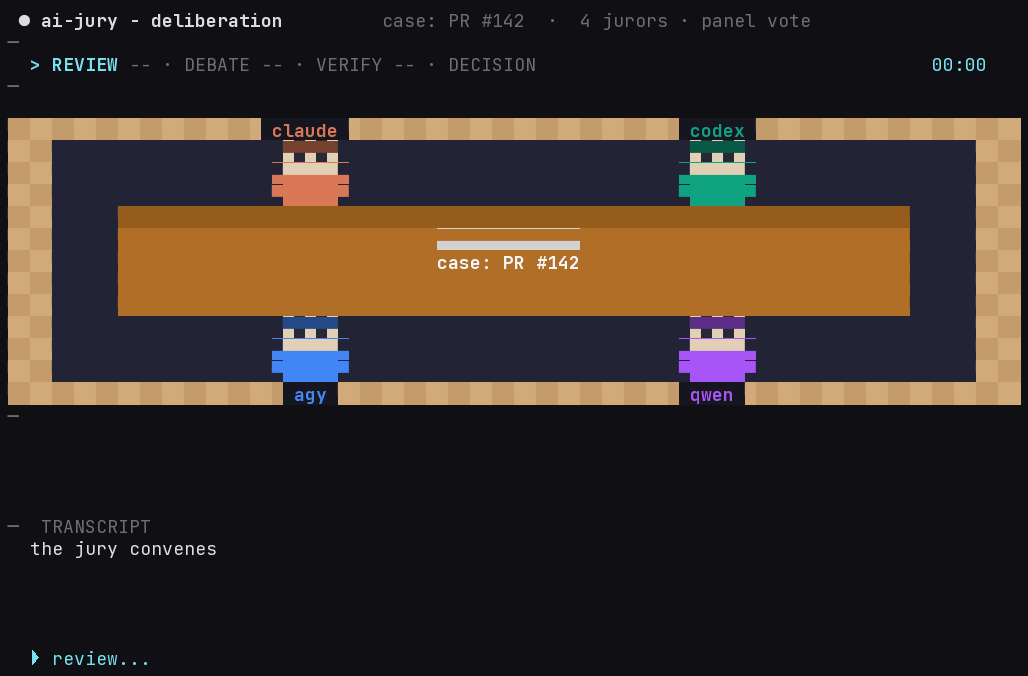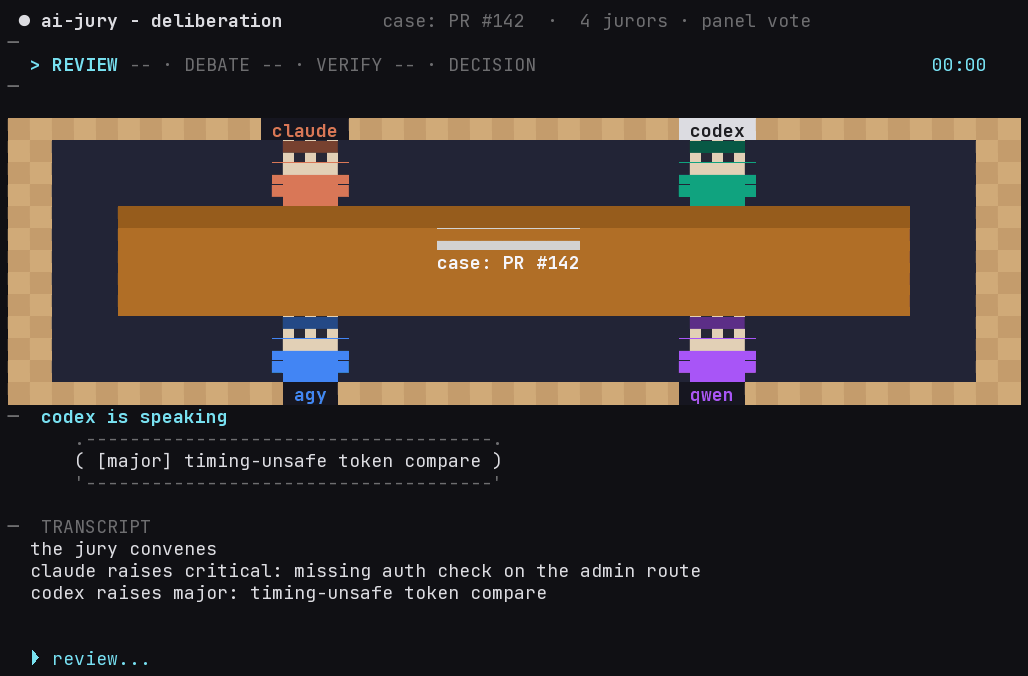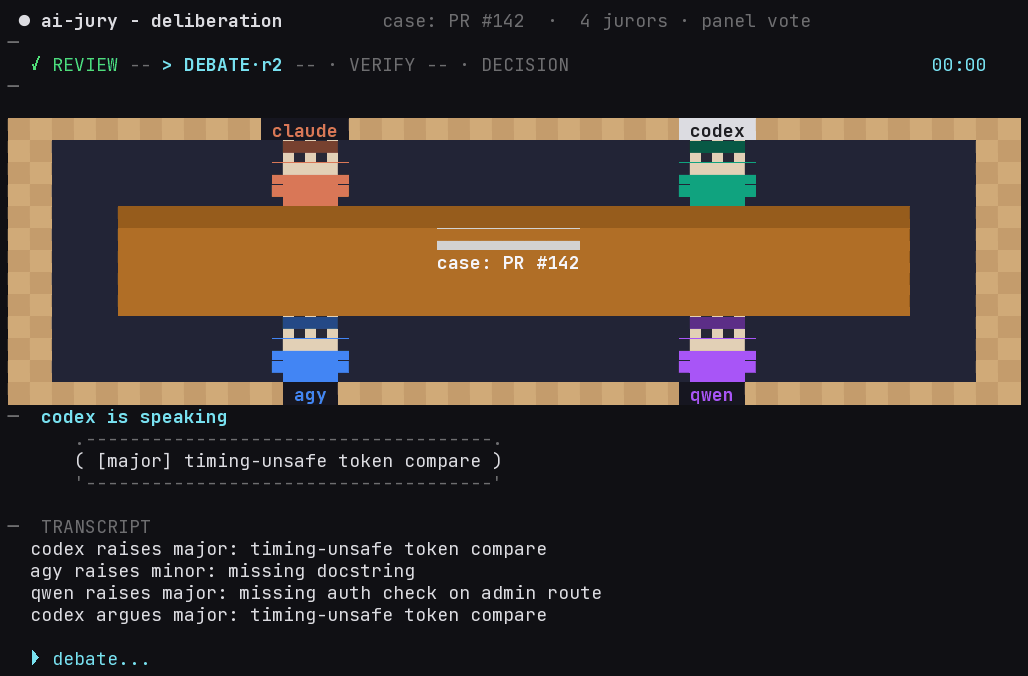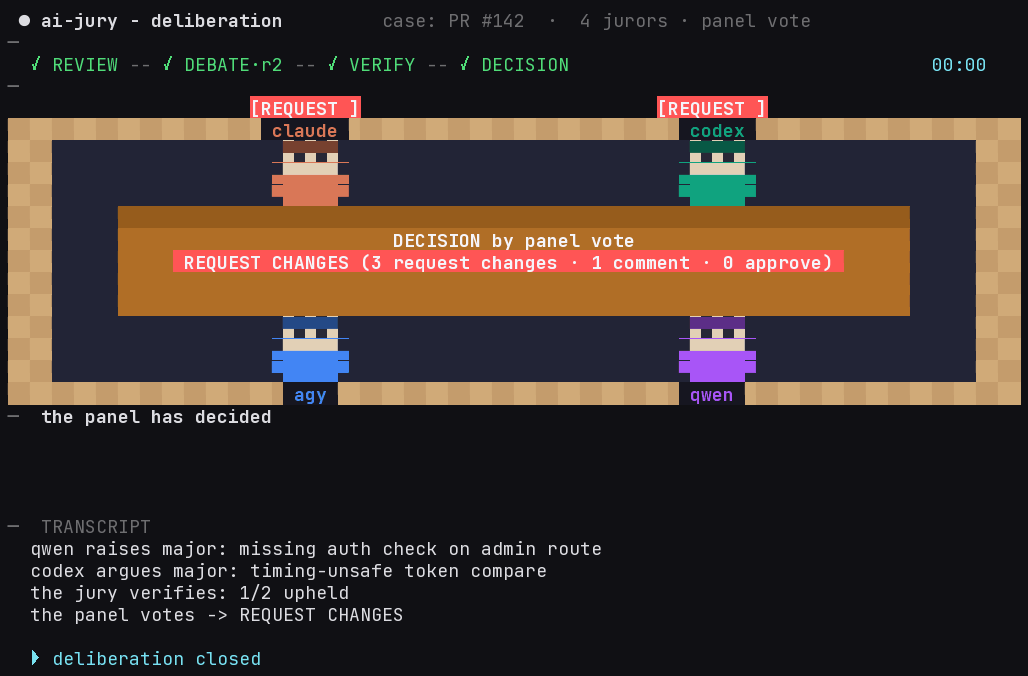
--theater-style pixel (truecolor terminal).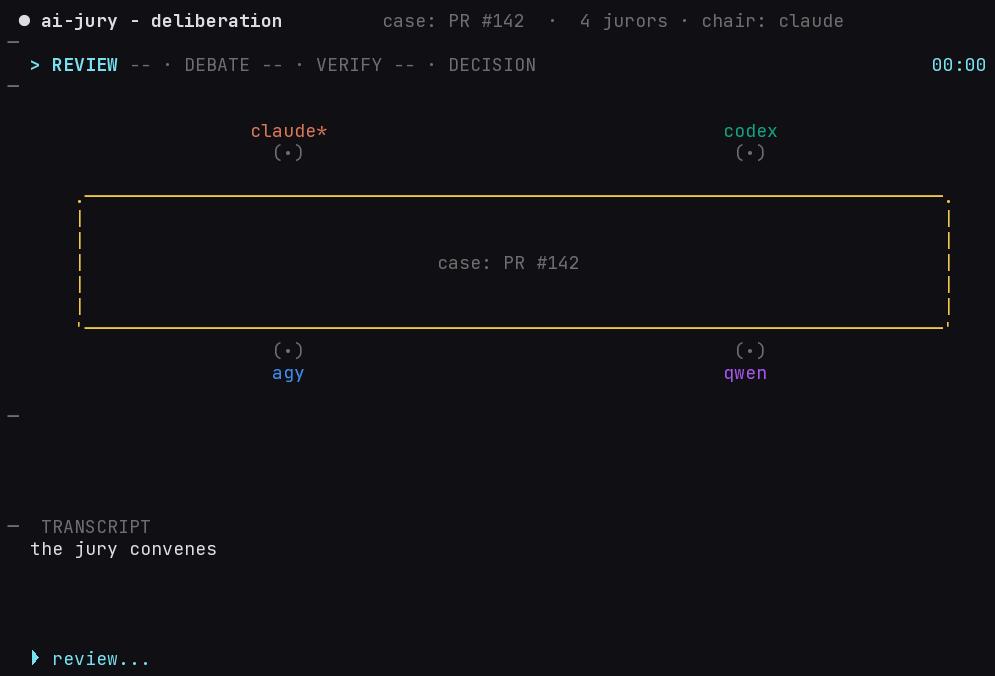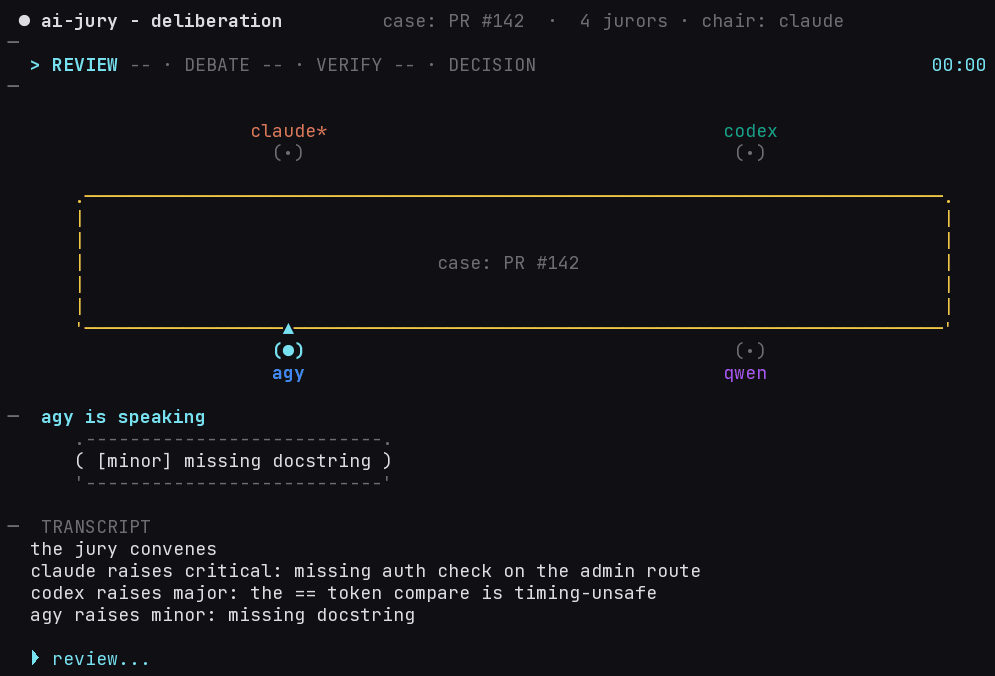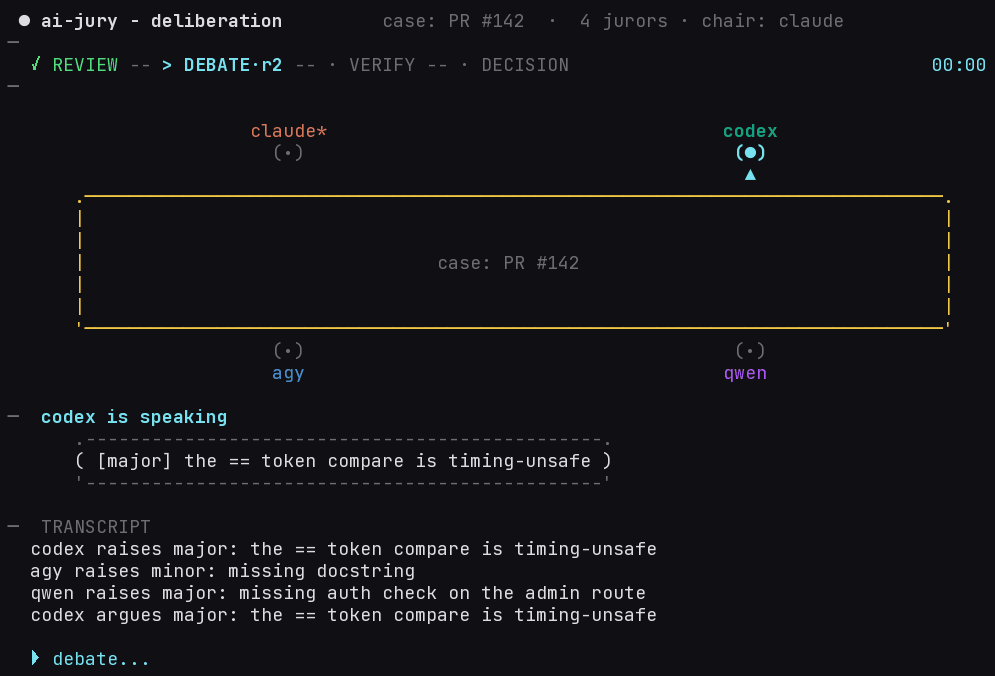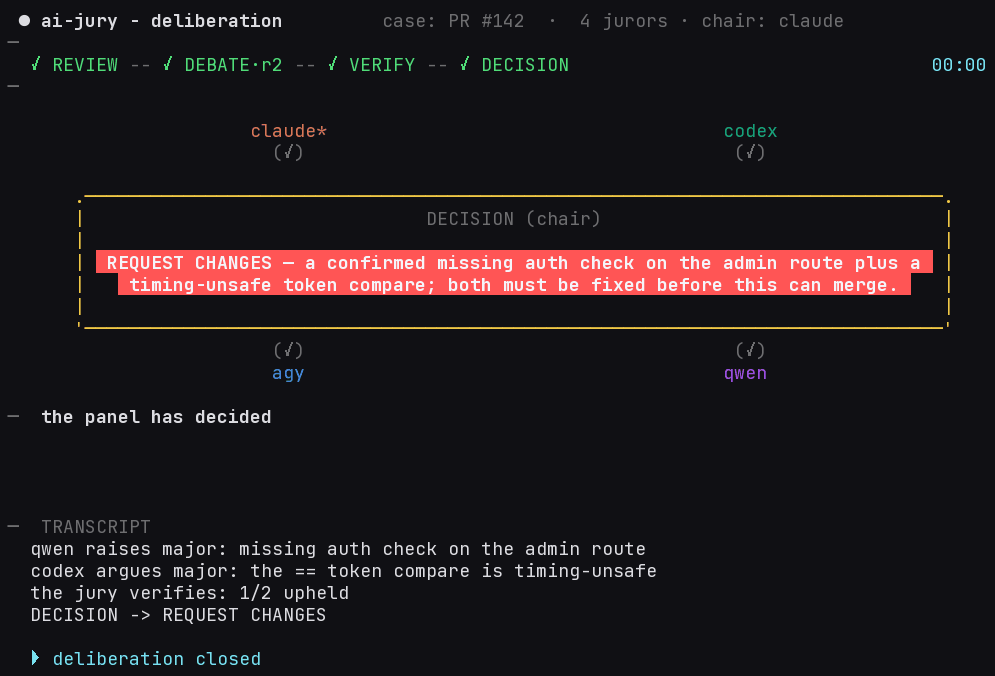
--theater.Round-table, not a bench
Jurors seat around the table and take turns; the table itself shows what's on it — the case, the verify checklist, or the decision banner.
Reflects the real run
It's a pure-stdlib ANSI side channel over the orchestrator's event stream — it never touches the report or the CI gate. Works for PRs and issues, chair or vote.
Degrades gracefully
Many jurors or a narrow terminal fall back to a compact roster; a non-interactive terminal falls back to the plain --live step stream.
jury --pr 123 --theater
also: --theater-style pixel · --issue 42 --theater · --decision vote
Where it fits
How ai-jury compares
Not a claim of superiority — a map to help you pick the right tool. A point-in-time snapshot (2026) of public docs; verify against current docs before deciding.
| Capability | ai-jury | Native-CLI peers | API-level | Hosted SaaS |
|---|---|---|---|---|
| Native CLI execution (per-vendor agent) | ✓ | ✓ | ✕ | ✕ |
| Multiple vendors / models | ✓ | ✓ | ✓ | ◐ |
| Consensus / debate rounds | ✓ | ✓ | ◐ | ◐ |
| Review an issue for completeness (not just diffs) | ✓ | ✕ | ✕ | ✕ |
| Verdict by panel vote or single chair | ✓ | ✕ | ✕ | ✕ |
| Verification pass (judges findings against the diff) | ✓ | ◐ | ✕ | ◐ |
| CI gating (non-zero on blocking) | ✓ | ◐ | ✕ | ✓ |
| Risk-aware auto-depth | ✓ | ✕ | ✕ | ◐ |
| Animated deliberation view (in-terminal) | ✓ | ✕ | ✕ | ✕ |
| Offline / local open-weight reviewer ($0) | ✓ | ◐ | ◐ | ✕ |
| No review server of its own (the diff goes only to the model endpoints you configure) | ✓ | ✓ | ◐ | ✕ |
| Secret redaction before send | ✓ | ◐ | ◐ | — |
| Auto-apply fixes | ◐ | ◐ | ✕ | ✓ |
| Hosted dashboard | ✕ | ✕ | ✕ | ✓ |
| Dependency footprint | stdlib-only | ◐ Node/Bun | ◐ Python | hosted |
✓ yes · ◐ partial / optional · ✕ no · — n/a
Use a hosted reviewer
CodeRabbit, Greptile, Copilot review — when you want a zero-maintenance, dashboard-driven product with auto-fix and are fine sending code to a third party.
Use an API-level tool
Star Chamber — when you want multi-model consensus over provider APIs. (ai-jury's hosted-API seats also need only an API key, no CLI install.)
Use ai-jury
When you want each reviewer to run as its native vendor CLI agent, a local-first, stdlib-only drop-in with debate + verification + CI gating — and the option to run fully offline at $0.
Full matrix & rationale in the ecosystem comparison.
Sample output
What lands on your PR
A trimmed real report from jury --mock --diff-file examples/sample.diff (deterministic, no live CLIs; its two mock seats are the default panel, claude and codex). The full, unedited report is the example run. A live run uses the same pipeline with the agent CLIs your jury.toml seats.
 AI Jury
One confirmed major issue.
Consensus findings
- major
src/example.py:42— unchecked return value may swallow an error reviewers: claude, codex
Disputed
- Missing docstring at
src/example.py:7— ruled a non-blocking nit.
Notable single-reviewer
- No test covers the error branch.
Show round-by-round transcript
Round 1 — independent reviews
claude · codex
Both independently flag src/example.py:42 major and :7 missing docstring minor.
Round 2 — cross-examination
AGREE — confirm the unchecked-return finding at :42.
DISPUTE — the missing-docstring finding is a nit, not blocking.
MISSED — no test covers the error branch.
🏛️ Synthesized by ai-jury · claude, codex — Cross-vendor multi-agent code review · ⭐ Star on GitHub · Add to your repo
The jury reviewing its own repository
A four-vendor panel (Claude, Codex, Antigravity + a free local Qwen) reviewed the whole repo as one diff — the verification round confirmed real defects, threw out the panel's own false positives, and even excluded a reviewer that refused to answer instead of scoring it as a pass.
"one reviewer returned only 'I can't assist with that request' — an abdication, not a review" — the chair, excluding a non-answer instead of counting it as a clean passRead the full live review →
Why excluding that reviewer matters
One reviewer didn't review — it replied only "I can't assist with that request." A naive panel would read "no findings" as "looks good" and count it as an APPROVE, so a refusal (or a timeout, or an error) silently becomes a green light. The chair instead recognised the non-answer as an abdication and dropped it from consensus; the other three reviewers carried the verdict. A single-reviewer tool has no such guard — this is the case for a panel in one moment.
Read more: Case study — a refusing reviewer → · the full verbatim report →
FAQ
Questions, answered
Is ai-jury a hosted service or SaaS?
No. ai-jury is a local-first CLI and skill that runs on your machine or in your CI. There is no dashboard and no ai-jury server; your diff goes only to the model endpoints you configure — vendor CLIs and APIs, or your own model server for local seats. A landing/docs site exists, but a hosted review SaaS is a deliberate non-goal.
Does ai-jury edit or auto-apply fixes to my code?
Never on its own. By design it reviews and reports. With --suggest-patches it can emit inspectable suggested patches for verified findings only; applying one is a separate command you run yourself (jury apply, which asks before it writes).
Can ai-jury review issues, not just pull requests?
Yes. jury --issue 42 convenes the same panel on a GitHub issue and judges it for completeness & clarity — reproduction steps, expected vs actual, scope/acceptance criteria, missing context — with a READY / NEEDS-INFO / UNCLEAR verdict instead of the PR's APPROVE / REQUEST CHANGES / COMMENT. Panel voting (--decision vote), live streaming (--live), and posting the verdict back (--post, via gh issue comment) all work for issues too.
Can ai-jury run completely offline and free?
Yes. Add a local open-weight model as a panel seat (vendor = "local" via Ollama, llama.cpp, vLLM, or LM Studio): jury init --preset offline scaffolds a local-only panel, and every review then runs on your own hardware at $0 — or mix one local seat with cloud CLIs for more vendor diversity. Only fetching or posting to GitHub (--pr, --post) goes through gh and the network; --diff-file needs neither.
Are these real API calls to the models?
It depends on the seat. By default ai-jury drives each vendor's own coding-agent CLI (claude and codex; agy only if you seat it) as a subprocess: a CLI seat runs the vendor's own agent, and the jury hands every seat the diff in its prompt, so no reviewer needs access to your repository. That is orchestration, not a raw model API call. A hosted-API seat (vendor = "anthropic-api", "openai-api", "google-api" or "xai-api", or "openai-compatible" for OpenRouter, DeepSeek, Groq and others) is a direct API call keyed by an API key, for CI or containers where installing an agent CLI isn't practical. A local seat (vendor = "local") calls your own model server, and vendor = "cli" wraps another coding CLI such as Aider or Goose.
What do I need installed to use ai-jury?
Python 3.11+ and at least one reviewer seat: an agent CLI (claude, codex; agy opt-in; cursor-agent or aider as a vendor = "cli" seat), a local model via Ollama, or a hosted API. A hosted-API key alone seats nothing: add an [[agent]] seat for it to jury.toml — vendor = "anthropic-api" with ANTHROPIC_API_KEY, say, or "openai-compatible" with OPENROUTER_API_KEY — and no CLI install is needed. The gh CLI is needed for --pr / --issue and for posting comments. The tool itself is stdlib-only — no third-party Python dependencies.
How does ai-jury keep secrets and untrusted diffs safe?
Reviewers read attacker-controlled diffs, so they get as little as each CLI allows. The claude seat has no tools at all; the codex seat runs a read-only sandbox but can still read files; agy is opt-in only and not in the default panel, because its sandbox does not confine it. Each native reviewer starts in an empty directory rather than your repository, diff-only context is the default, and secret redaction is on before anything is sent. See the security model.
Not a hosted SaaS. This is a local-first CLI + skill, not a hosted review service or a general multi-agent framework. It reviews and reports; it can emit inspectable suggested patches for verified findings, but never applies them on its own — jury apply is a command you run.
Convene the jury on your next PR.
One command installs it. Bring your own agents, or run it free and fully offline.
pipx install ai-jury